REKI: Registering Knowledge in VLAs
We introduce REKI, a 2.4B vision-language-action model (VLA) pretrained exclusively on public data that sets a new Pareto frontier between performance and model size: on LIBERO-Plus, RoboTwin Clean2Rand and RoboCasa365, it is outperformed only by models about twice its size.
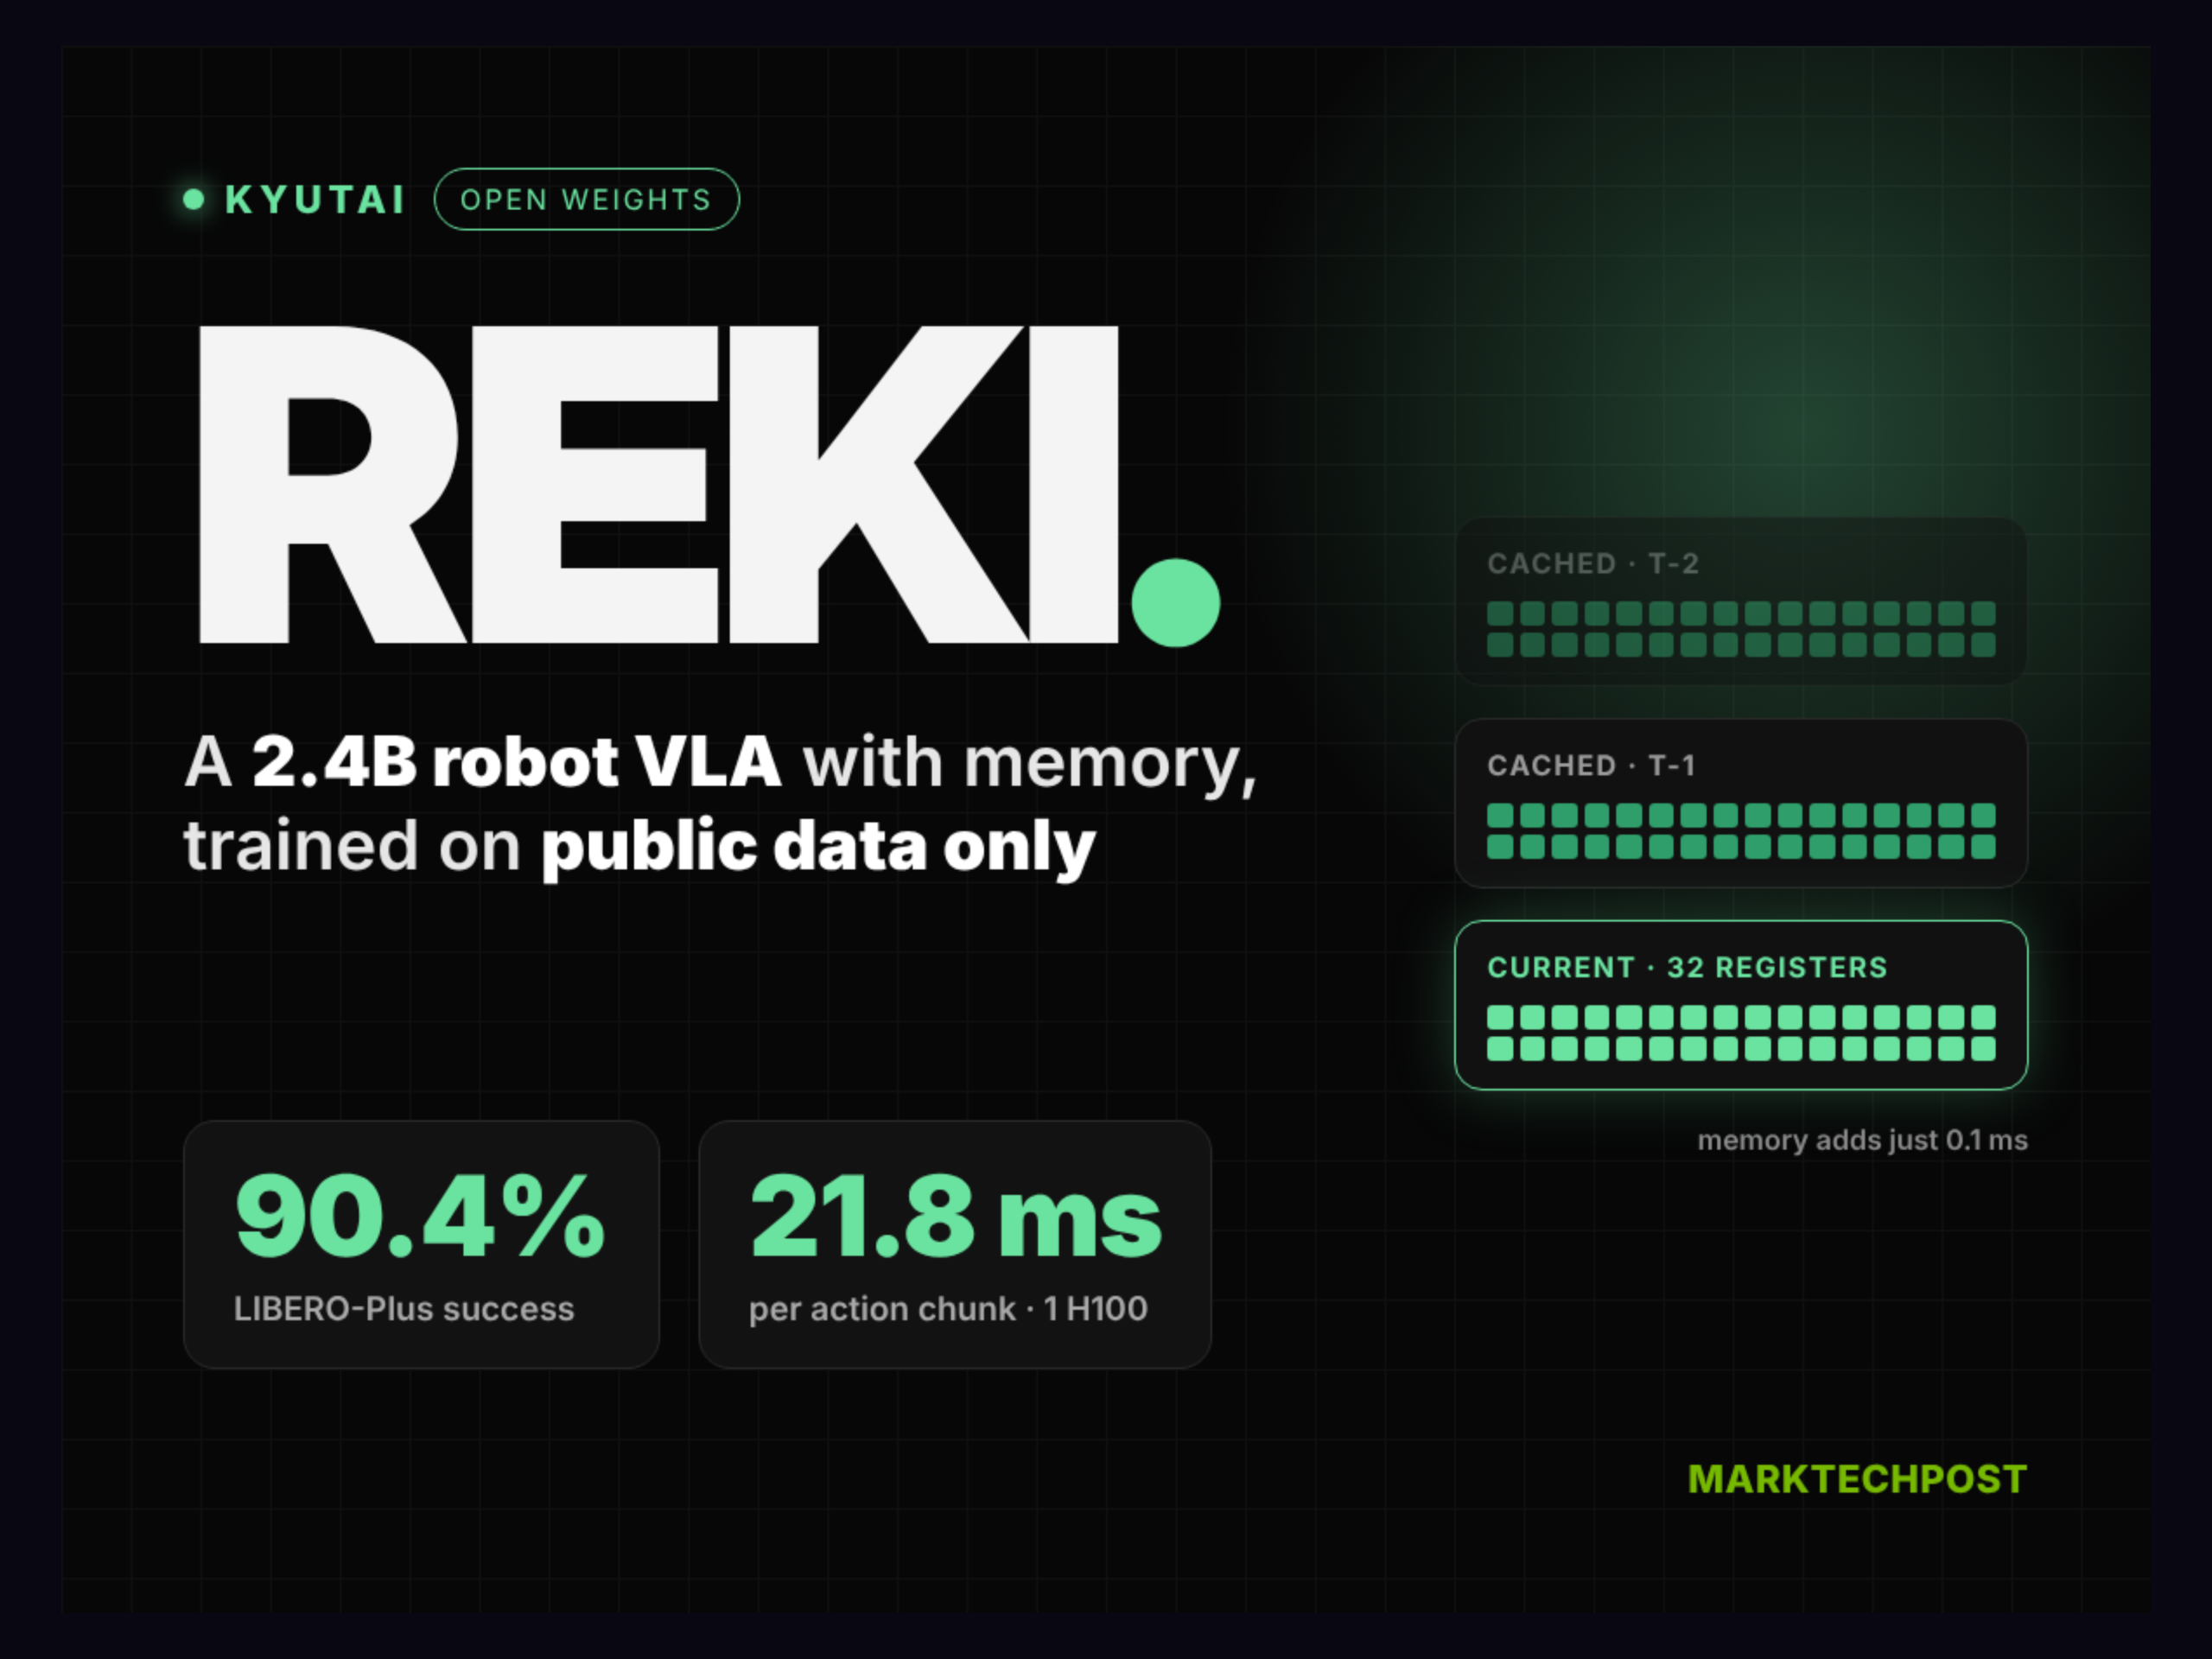
Key points
- REKI consists of a vision-language model (VLM) followed by a flow-matching action expert, and is pretrained on a curated mixture of public robot, egocentric human and vision-language data.
- Additionally, we endow it with a memory that gives the policy access to its recent past at negligible cost: a few register tokens in the action expert summarise the output of the VLM at each frame and persist in the expert's cache.
- Kyutai, with Inria and École des Ponts, has released REKI, a 2.4B vision-language-action model (VLA) for robot manipulation.
- The REKI vision-language-action model is pretrained only on public data.
Sources (2)
- [1]REKI: Registering Knowledge in VLAsarXiv (AI, ML, NLP, CV, robotics, multi-agent) · Oct 15, 04:34 PM
We introduce REKI, a 2.4B vision-language-action model (VLA) pretrained exclusively on public data that sets a new Pareto frontier between performance and model size: on LIBERO-Plus, RoboTwin Clean2Rand and RoboCasa365, it is outperformed only by models about twice its size.
REKI consists of a vision-language model (VLM) followed by a flow-matching action expert, and is pretrained on a curated mixture of public robot, egocentric human and vision-language data.
- [2]Meet Kyutai REKI: The 2.4B VLA Model Bringing Efficient Memory to Robot ManipulationMarkTechPost · Oct 17, 08:22 PM
Kyutai, with Inria and École des Ponts, has released REKI, a 2.4B vision-language-action model (VLA) for robot manipulation.
The REKI vision-language-action model is pretrained only on public data.
Extractive summary: sentences quoted from the sources.
Before this
- Oct 15, 2026NVIDIA Nemotron 3.5 Super VL Powers Specialized Agents with Multimodal Reasoning
- Oct 15, 2026Fast-VLA: You Only Think Once for Robot Manipulation
- Oct 15, 2026VLA-$Δ$: Learning Physical State Transition for Vision-Language-Action Models
- Oct 15, 2026Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio
- Oct 14, 2026NVIDIA/TensorRT-LLM v1.4.0rc0
- Oct 14, 2026Introducing Timestral