Models
New and updated models, and how they score.
Introducing Timestral
Timestral, Mistral’s first family of time-series foundation models, delivers state-of-the-art probabilistic, multivariate forecasts with just 209M parameters, outperforming larger models on key benchmarks while supporting past and future covariates.

deepseek-ai/DeepSeek-V4.1-Flash-1017
deepseek-ai published the model DeepSeek-V4.1-Flash-1017 on Hugging Face.

Nemotron 3.5 Bolt, Muse Spark Open, and a Fast LFM2.5 24B
Nemotron 3.5, with a closer look at Bolt and its “native 2-bit” quantization

nvidia/NVIDIA-Nemotron-Labs-Dory1.0-4B-MXFP8
nvidia published the model NVIDIA-Nemotron-Labs-Dory1.0-4B-MXFP8 on Hugging Face.

tencent/Hy-Memory-30B-A3B
tencent published the model Hy-Memory-30B-A3B on Hugging Face.

black-forest-labs/flux-3-image-klein-comfy
black-forest-labs published the model flux-3-image-klein-comfy on Hugging Face.

Gemini 4 Argon: Built to solve your hardest problems
Gemini 4 Argon: Built to solve your hardest problems

NVIDIA Nemotron 3.5 Super VL Powers Specialized Agents with Multimodal Reasoning
NVIDIA Nemotron 3.5 Super VL is an open, customizable multimodal model for these specialized workflows.
llm-tools-datasette 0.1.1
When I switched LLM over to httpx2 in LLM 0.33 I forget that this would break any plugins which used https without directly depending on it. llm-tools-datasette was one of those plugins, now fixed.

Granite Switch 4.1: Chat, Decisions, and Speech from One Endpoint
Specifically, Granite-Switch-4.1-8B and -30B models are configured to include:

AI agents have bad taste in long-term decisions and a new benchmark proves it
A new benchmark called Taste-Bench tests how well AI agents make strategic choices during long-running tasks.

autotrust/AutoTrust-JEV-27B-v1.1
autotrust published the model AutoTrust-JEV-27B-v1.1 on Hugging Face.
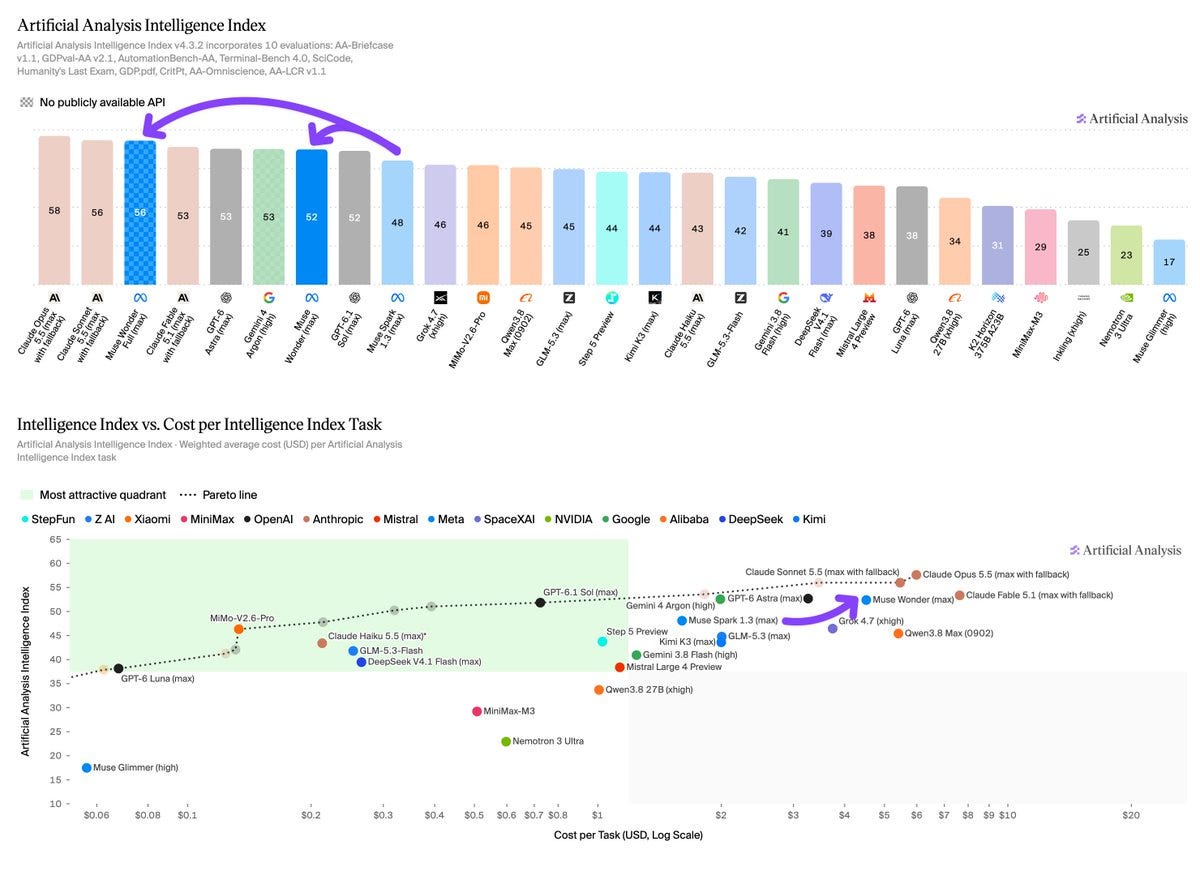
[AINews] Meta Muse Wonder & Wonder Full: MSL’s Claude 5.5-tier Frontier Model
We have been coveringe MSL’s 14 month journey to becoming a frontier lab, but only today did the final ball drop: Meta’s Muse Wonder to match Spark and Glimmer, the way that OpenAI has Sol/Terra/Luna and Anthropic has Opus/Sonnet/Haiku.
DeepSeek V4.1 Flash 1017 vs V4.1 Flash, Pi vs DeepSeek Harness: results on my 10 coding tasks
TL;DR: I ran the new DeepSeek V4.1 Flash 1017 on my personal coding benchmark, and it’s really good: 100% on high for under 5 cents a task.

Grok Voice 3.0 from SpaceXSI outscores OpenAI and Google on speech-to-speech index
Elon Musk’s artificial intelligence company SpaceXSI, formerly xAI, today released Grok Voice 3.0, a new version of the speech-to-speech model behind its Voice Agent API.
What is wrong with AI writing - ICLR edition [D]
The reason I think it's tricky is that "clearly AI writing" is not the right way to critique - AI "editing" of writing is allowed.

Sharing my ultimate krea 2 Asian Character Lora
Unfortunately I don't have any plan to create any new character krea 2 in near future (since krea 3 is very near to be released as open weights, but I might update the old krea 2 lora to refine the dataset when I see some bad seed/result.

Continuous accountability for Verified bots
The same is true for bots: verifying who operates it creates accountability, but trust depends on what it does next.

microsoft/UserRepGen-4B
microsoft published the model UserRepGen-4B on Hugging Face.

ibm-granite/granite-switch-4.1-30b
ibm-granite published the model granite-switch-4.1-30b on Hugging Face.

Elorian’s first AI model wants to reason with images, not just about them
according to Elorian's evaluations, Glimpse outperforms even GPT-6 Astra on scientific chart reasoning and short-form video captioning, with competitive results on other visual reasoning tasks.

allenai/HiRO-ACEv2
allenai published the model HiRO-ACEv2 on Hugging Face.
 Video
Rebuilding CI for AI-Scale Commit Volume — Gautam Korlam, SonarSource
A coding agent can produce changes faster than the queues that test, review and merge them.
SuperLocalMemory
Agent memory with Laya, Jev + Google Gemma

nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-NVFP4-LiLiCorr
nvidia published the model NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-NVFP4-LiLiCorr on Hugging Face.
llm-echo 0.5
I'm working towards a new LLM release, and testing PRs caused me to revisit the llm-echo debug plugin.

Apertus 1.5 Release Notes
Apertus 1.5 is a continued pretraining of the first generation model: adding 4 trillion tokens of text and multimodal training data to the 8B model and 2 trillion tokens to the 70B model, for a total of 19T and 17T, respectively.
Gemini 4 Argon for Robotics
Gemini 4 Argon marks a step change in physical understanding, code generation, and visual-semantic reasoning—unlocking new workflows across the robotics stack and accelerating progress toward physical AGI.

lodestones/MOSS-Image-SFT-8-steps-dmd
lodestones published the model MOSS-Image-SFT-8-steps-dmd on Hugging Face.
Alignment on SOTA Chinese Models like Qwen 3.8 Flash Next / GLM 5.3 Flash
What is your experience on alignment with models like Qwen 3.8 27B or Qwen 125B Next Flash?

inclusionAI/Ling-3.1-flash
inclusionAI published the model Ling-3.1-flash on Hugging Face.

Run fast, private agents on-device with LFM2.5-24B-A2B
Best-in-class agent: Competitive with Qwen3.6-35B-A3B, a model with ~50% more total and active parameters, on agentic and tool-use tasks, scoring 48.09 on LiveClaw versus 38.19.

nvidia/Muse-Spark-Open-816B-A42B-DFlash2
nvidia published the model Muse-Spark-Open-816B-A42B-DFlash2 on Hugging Face.

autotrust/Qwen3.8-27B-NVFP4-DGX-SPARK
autotrust published the model Qwen3.8-27B-NVFP4-DGX-SPARK on Hugging Face.

AI labs report benchmark scores 6.4% higher than independent testers, on average
I've been building whatmodel.sh, an open source AI leaderboard, and wanted to see how a labs' own benchmark scores compare with independent testers.

nvidia/Nemotron-3.5-Rerank-8B-BF16
nvidia published the model Nemotron-3.5-Rerank-8B-BF16 on Hugging Face.

Qwen Flash Next potential SOTA Q2 nobody talks about
Also enhanced loop resitance is advertised.
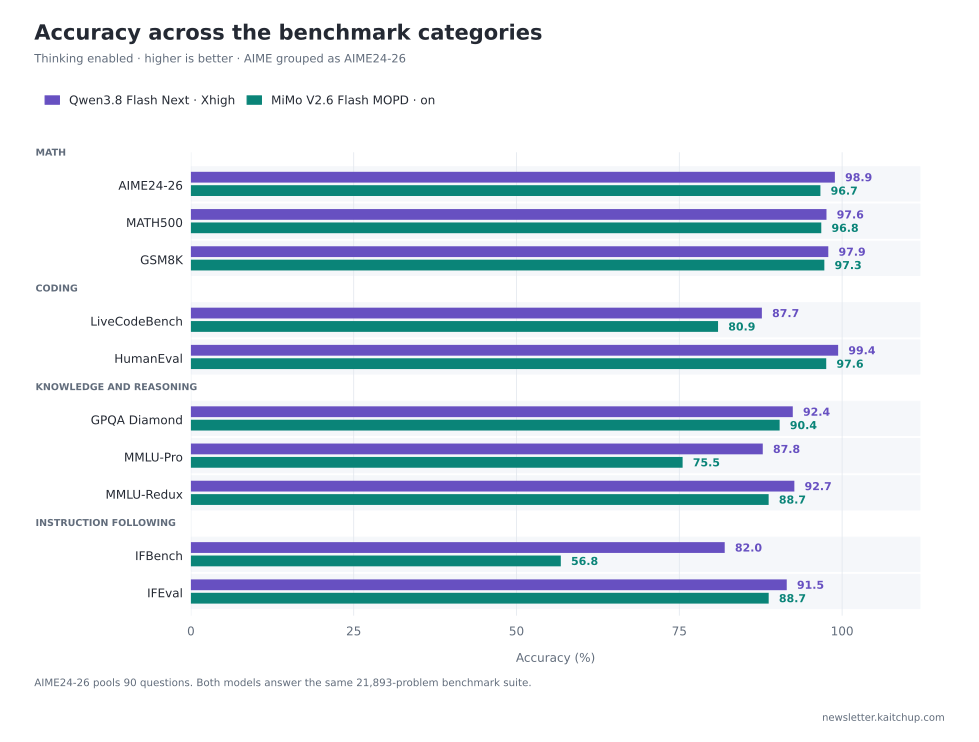
MiMo V2.6 Flash vs Qwen3.8 Flash Next: Accuracy, Token Efficiency and Memory Use
Xiaomi’s MiMo V2.6 Flash is a large mixture-of-experts (MoE) model with 309 billion parameters, of which 15 billion are activated per token.

Tyger: open-weights streaming ASR + full-duplex turn-control in one model
Hi r/LocalLLaMA, we're releasing Tyger, a small model that handles full-duplex turn-control for voice agents.

New TTS king in town: Fish's Drama 3 35B3A!
Yesterday Fish released this incredible text-to-speech model, so naturally I spent the rest of the day building a great demo for them :D The model is a chunky MoE (35B3A), but it runs well on a DGX Spark.

The actual state of open-weight models vs. frontier models
It's clear that today’s SOTA (state-of-the-art) models remain ahead of open-source models.
Z.ai GLM-Legal Beats Claude Fable 5 and Kimi K3 on Harvey LAB
GLM-Legal is a legal AI model from Z.ai, built on GLM-5.3-Flash and trained for agentic legal work.

nvidia/ARDY-SOMA-RP-30FPS-KimodoRep-Horizon60
nvidia published the model ARDY-SOMA-RP-30FPS-KimodoRep-Horizon60 on Hugging Face.

nvidia/Kimodo-SOMA-RP-ArdyRep-v1.2
nvidia published the model Kimodo-SOMA-RP-ArdyRep-v1.2 on Hugging Face.

HiRO-ACEv2: Simulating extreme weather at 3 km resolution for a fraction of the cost
We introduce HiRO-ACEv2, the newest update to our High Resolution Output Ai2 Climate Emulator (HiRO-ACE) system.
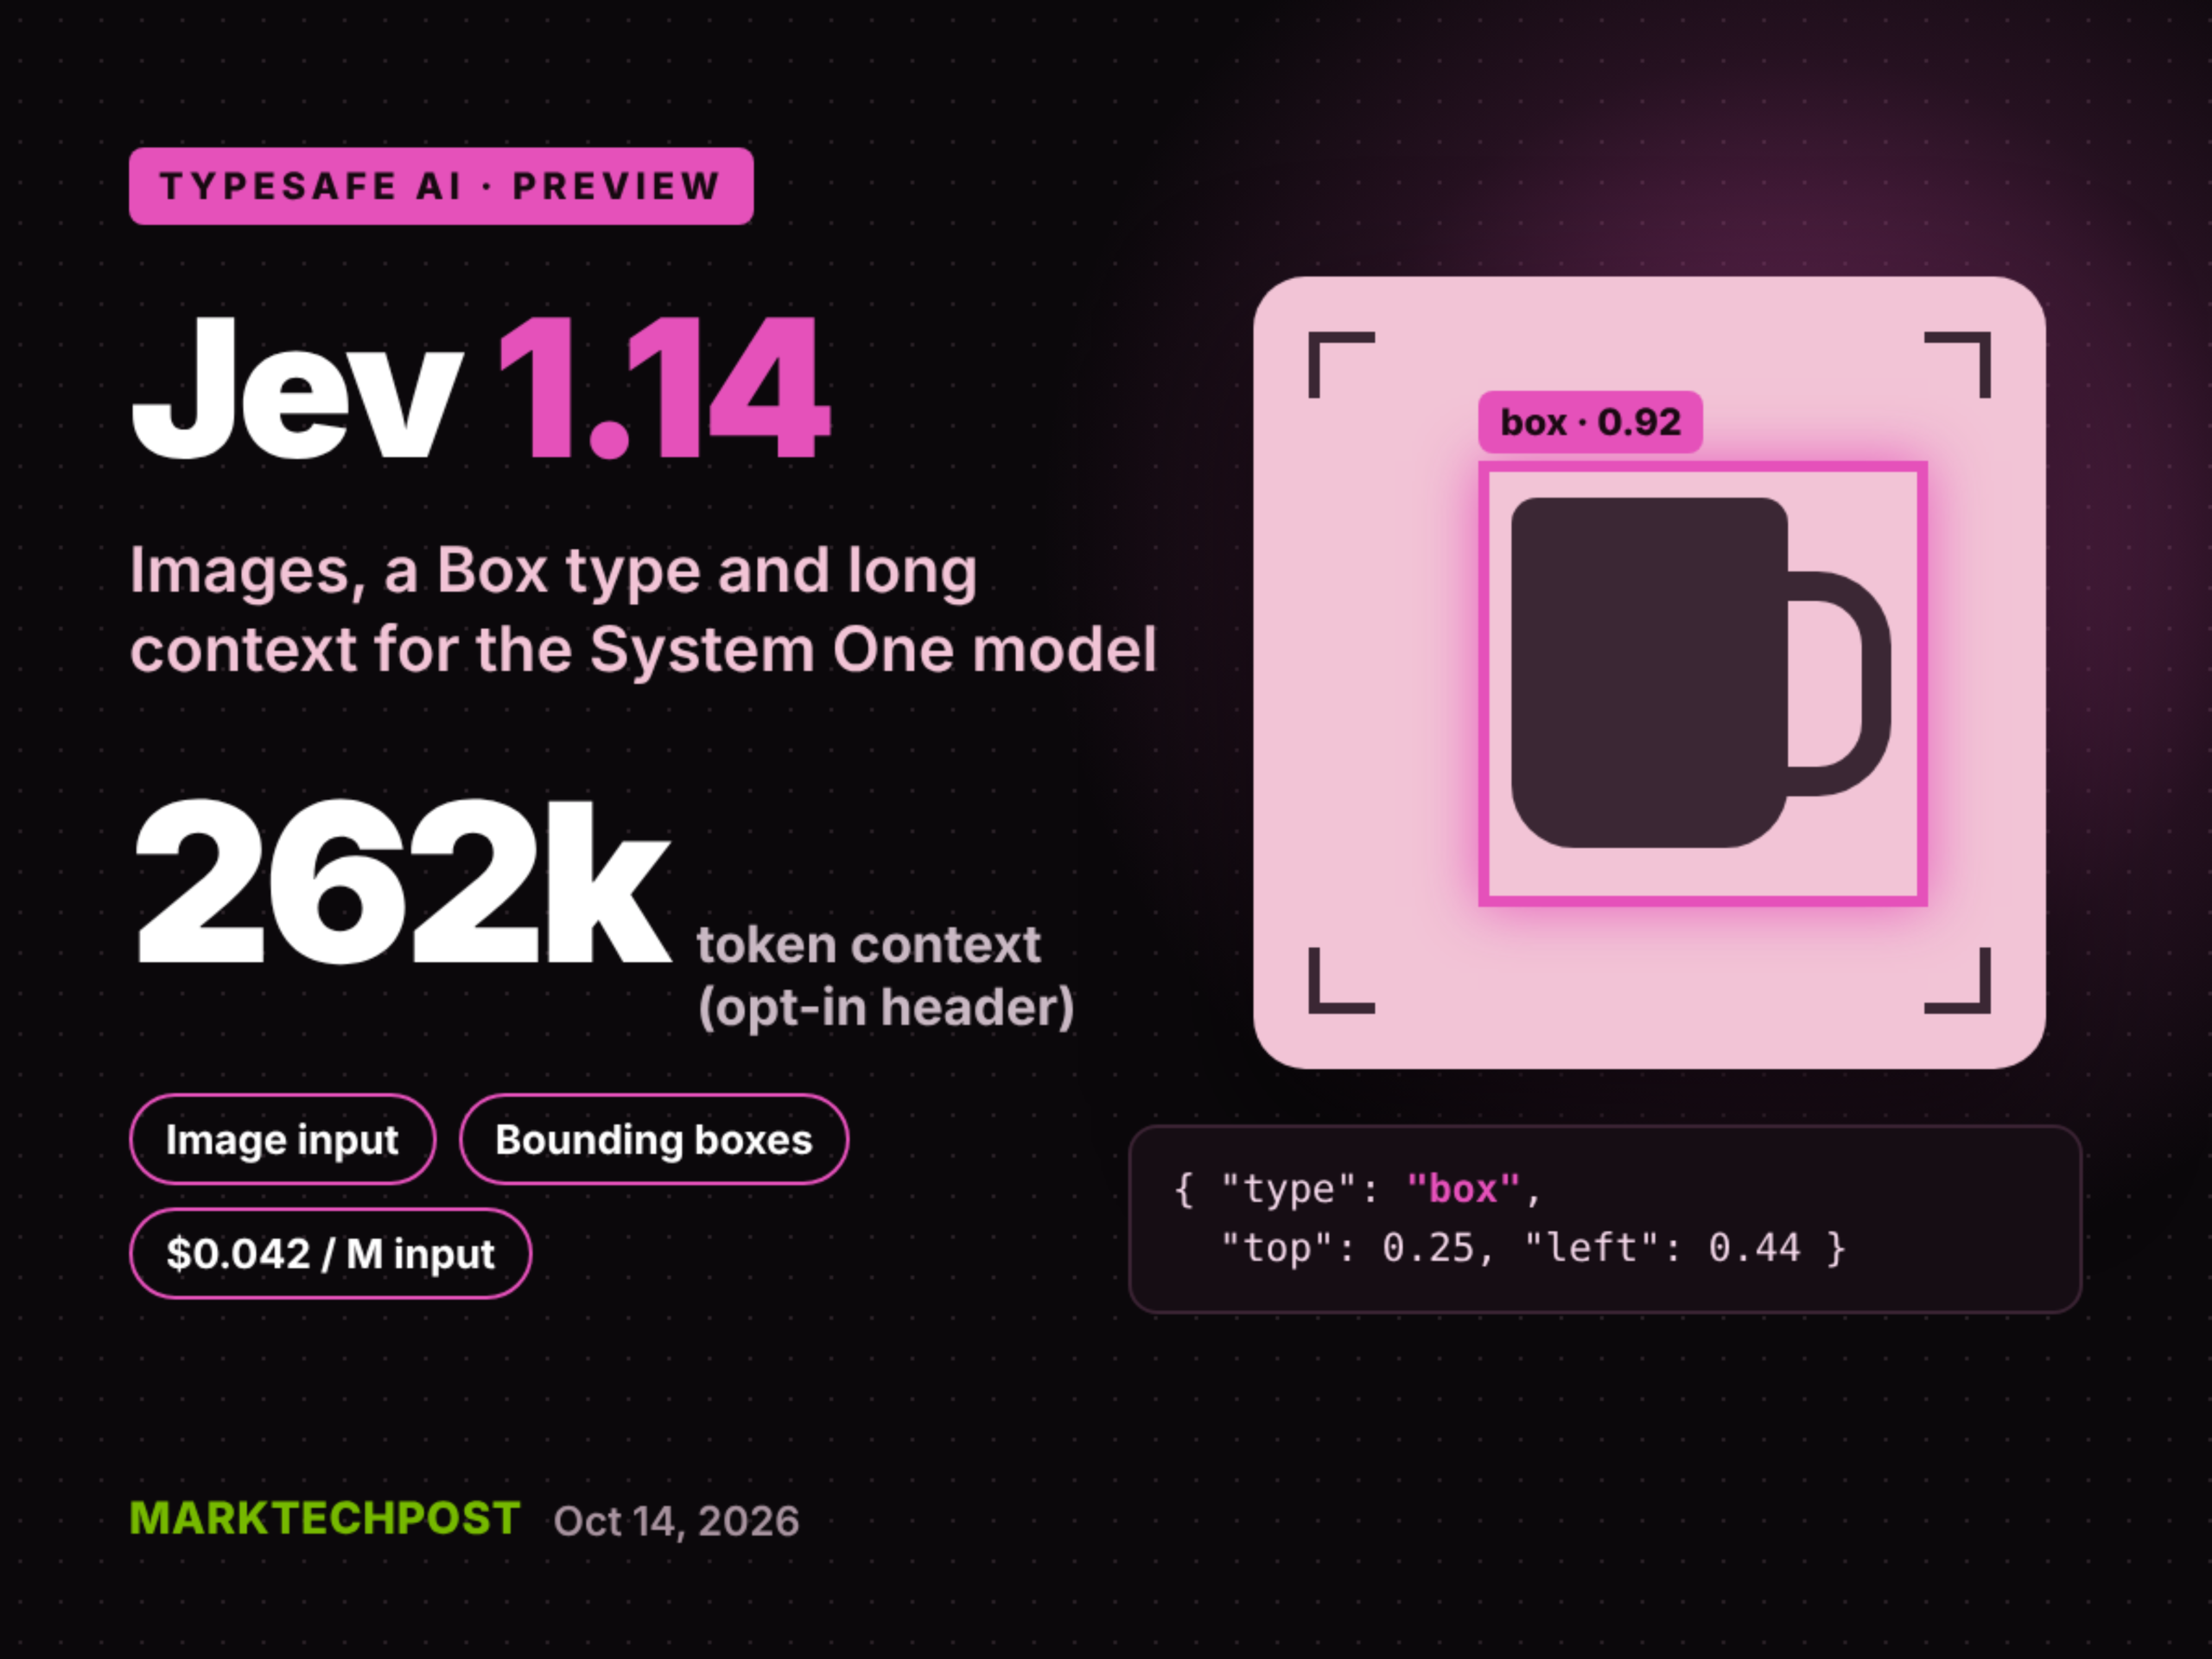
TypeSafe AI Releases Jev 1.14 With Images, Box Type and 262k Context
TypeSafe AI has released Jev 1.14, a new version of its System One decision model.
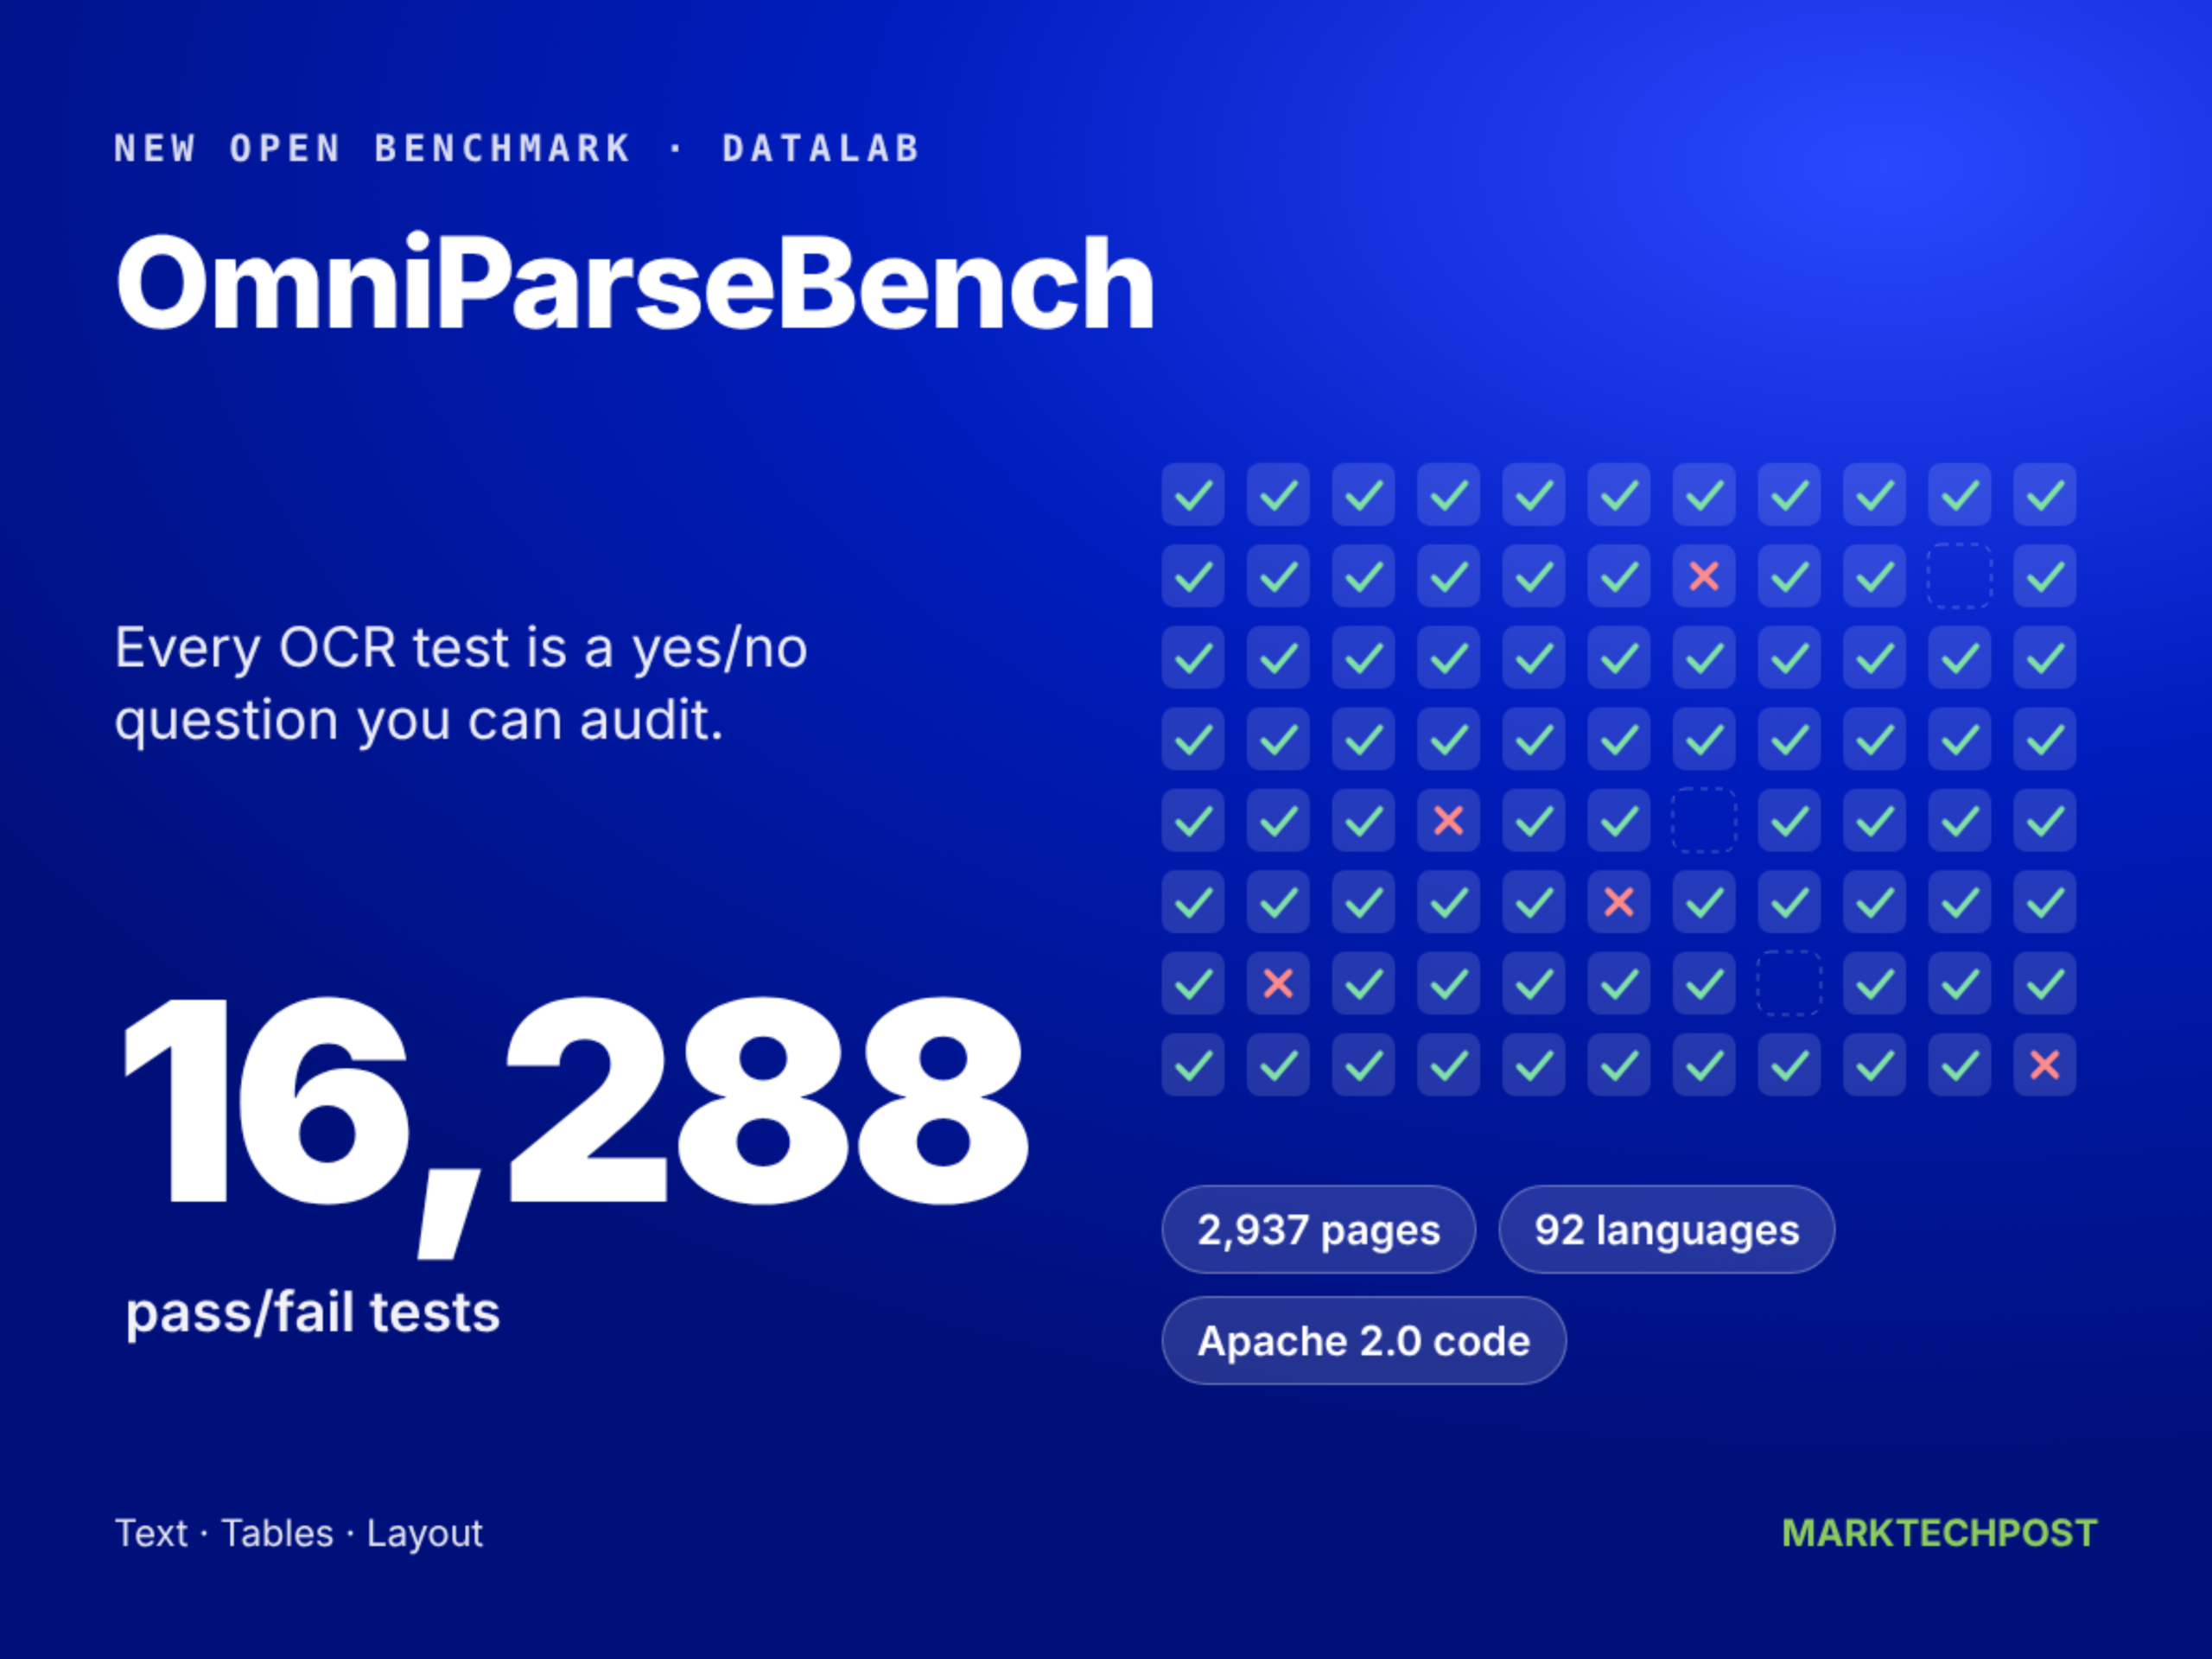
Datalab Releases OmniParseBench: An Open OCR Benchmark With 16,288 Pass/Fail Tests to Audit OCR Parsers
Datalab has released OmniParseBench, an open OCR benchmark for document parsers.
Why do we have models under 15b so rarely anymore?
I wonder when will we get the next sub 14b model from a SOTA lab