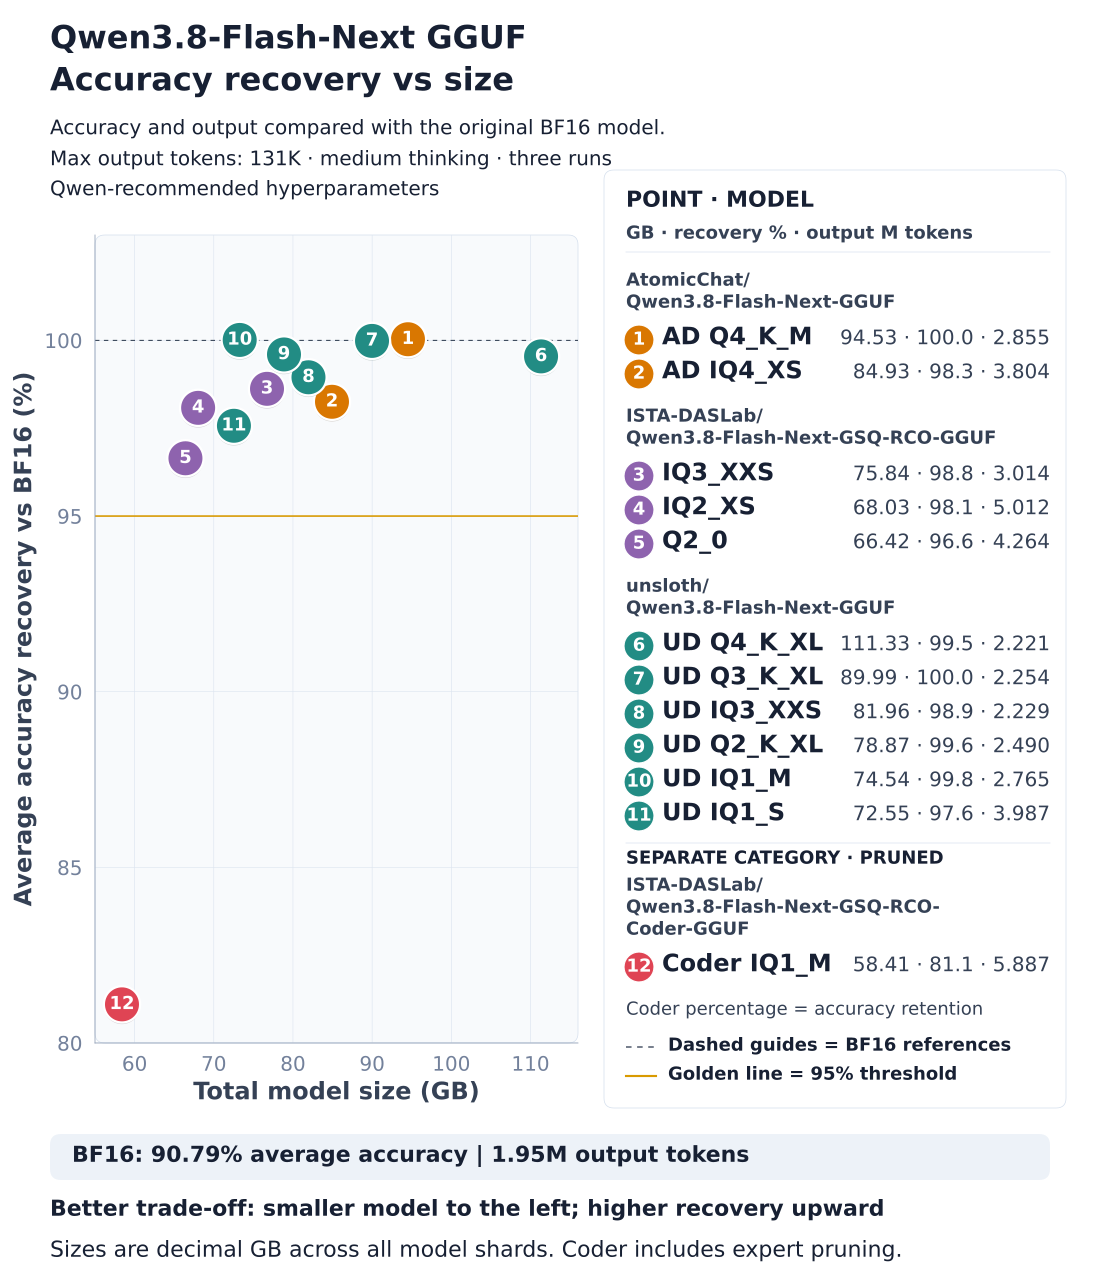
Qwen Flash Next potential SOTA Q2 nobody talks about
Also enhanced loop resitance is advertised.

Proof1 community thread
Key points
- Bold claims and signle contributor were the things why I was initially reluctunt to check the claims myselfm hovewer that potential space savings were impossible to resist so I downloaded GYRO-M and played around with it for a little while.
- Vision: yes, took it from ISTA lab IQ3XXS quant
- Subjective impression - more stable than ISTA q2 quants, less stable than ISTA q3 because of Cyrillics problem
- As fast as ISTA 2 bit quants
Sources (1)
- [1]Qwen Flash Next potential SOTA Q2 nobody talks aboutr/LocalLLaMA (top, daily) · Oct 16, 09:08 AM
Also enhanced loop resitance is advertised.
Bold claims and signle contributor were the things why I was initially reluctunt to check the claims myselfm hovewer that potential space savings were impossible to resist so I downloaded GYRO-M and played around with it for a little while.
Extractive summary: sentences quoted from the sources.
Hype check
Independently evaluated7 independent looks since
- Evaluation · Oct 16, 2026The actual state of open-weight models vs. frontier models
- Evaluation · Oct 16, 2026To reviewers: do you upload your review to an AI? (NOT the paper itself) [D]
- Evaluation · Oct 16, 2026Why do we have models under 15b so rarely anymore?
- Evaluation · Oct 16, 2026FLUX 3 vs KREA 2 vs Z image turbo vs Qwen 2.1
- Evaluation · Oct 16, 2026Step 5 Preview
- Evaluation · Oct 16, 2026PresenceBench: An Exploratory Evaluation of Large Language Model Adaptation to User State
Before this
- Oct 16, 2026Welcome Beam: a 501B open model you can own, customize, and scale
- Oct 15, 2026Granite Switch 4.1: Chat, Decisions, and Speech from One Endpoint
- Oct 15, 2026huggingface/transformers v5.20.0: Release v5.20.0
- Oct 15, 2026NVIDIA Nemotron 3.5 Super VL Powers Specialized Agents with Multimodal Reasoning
- Oct 15, 2026Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio
- Oct 14, 2026New model from Telperion: Qwen3.8-27B-MLA & Qwen3.8-27B-GLA-g2. 4x smaller KV cache, smarter, and more efficient reasoning.